


ai
Jun 29, 2026
Most AI failures in data pipelines aren't model failures — they're architecture failures. Ten anti-patterns for keeping LLMs out of the parts of your pipeline that need to be deterministic, cheap, and reproducible.

Written By
Andrey Kozichev
data engineering
Sep 8, 2026
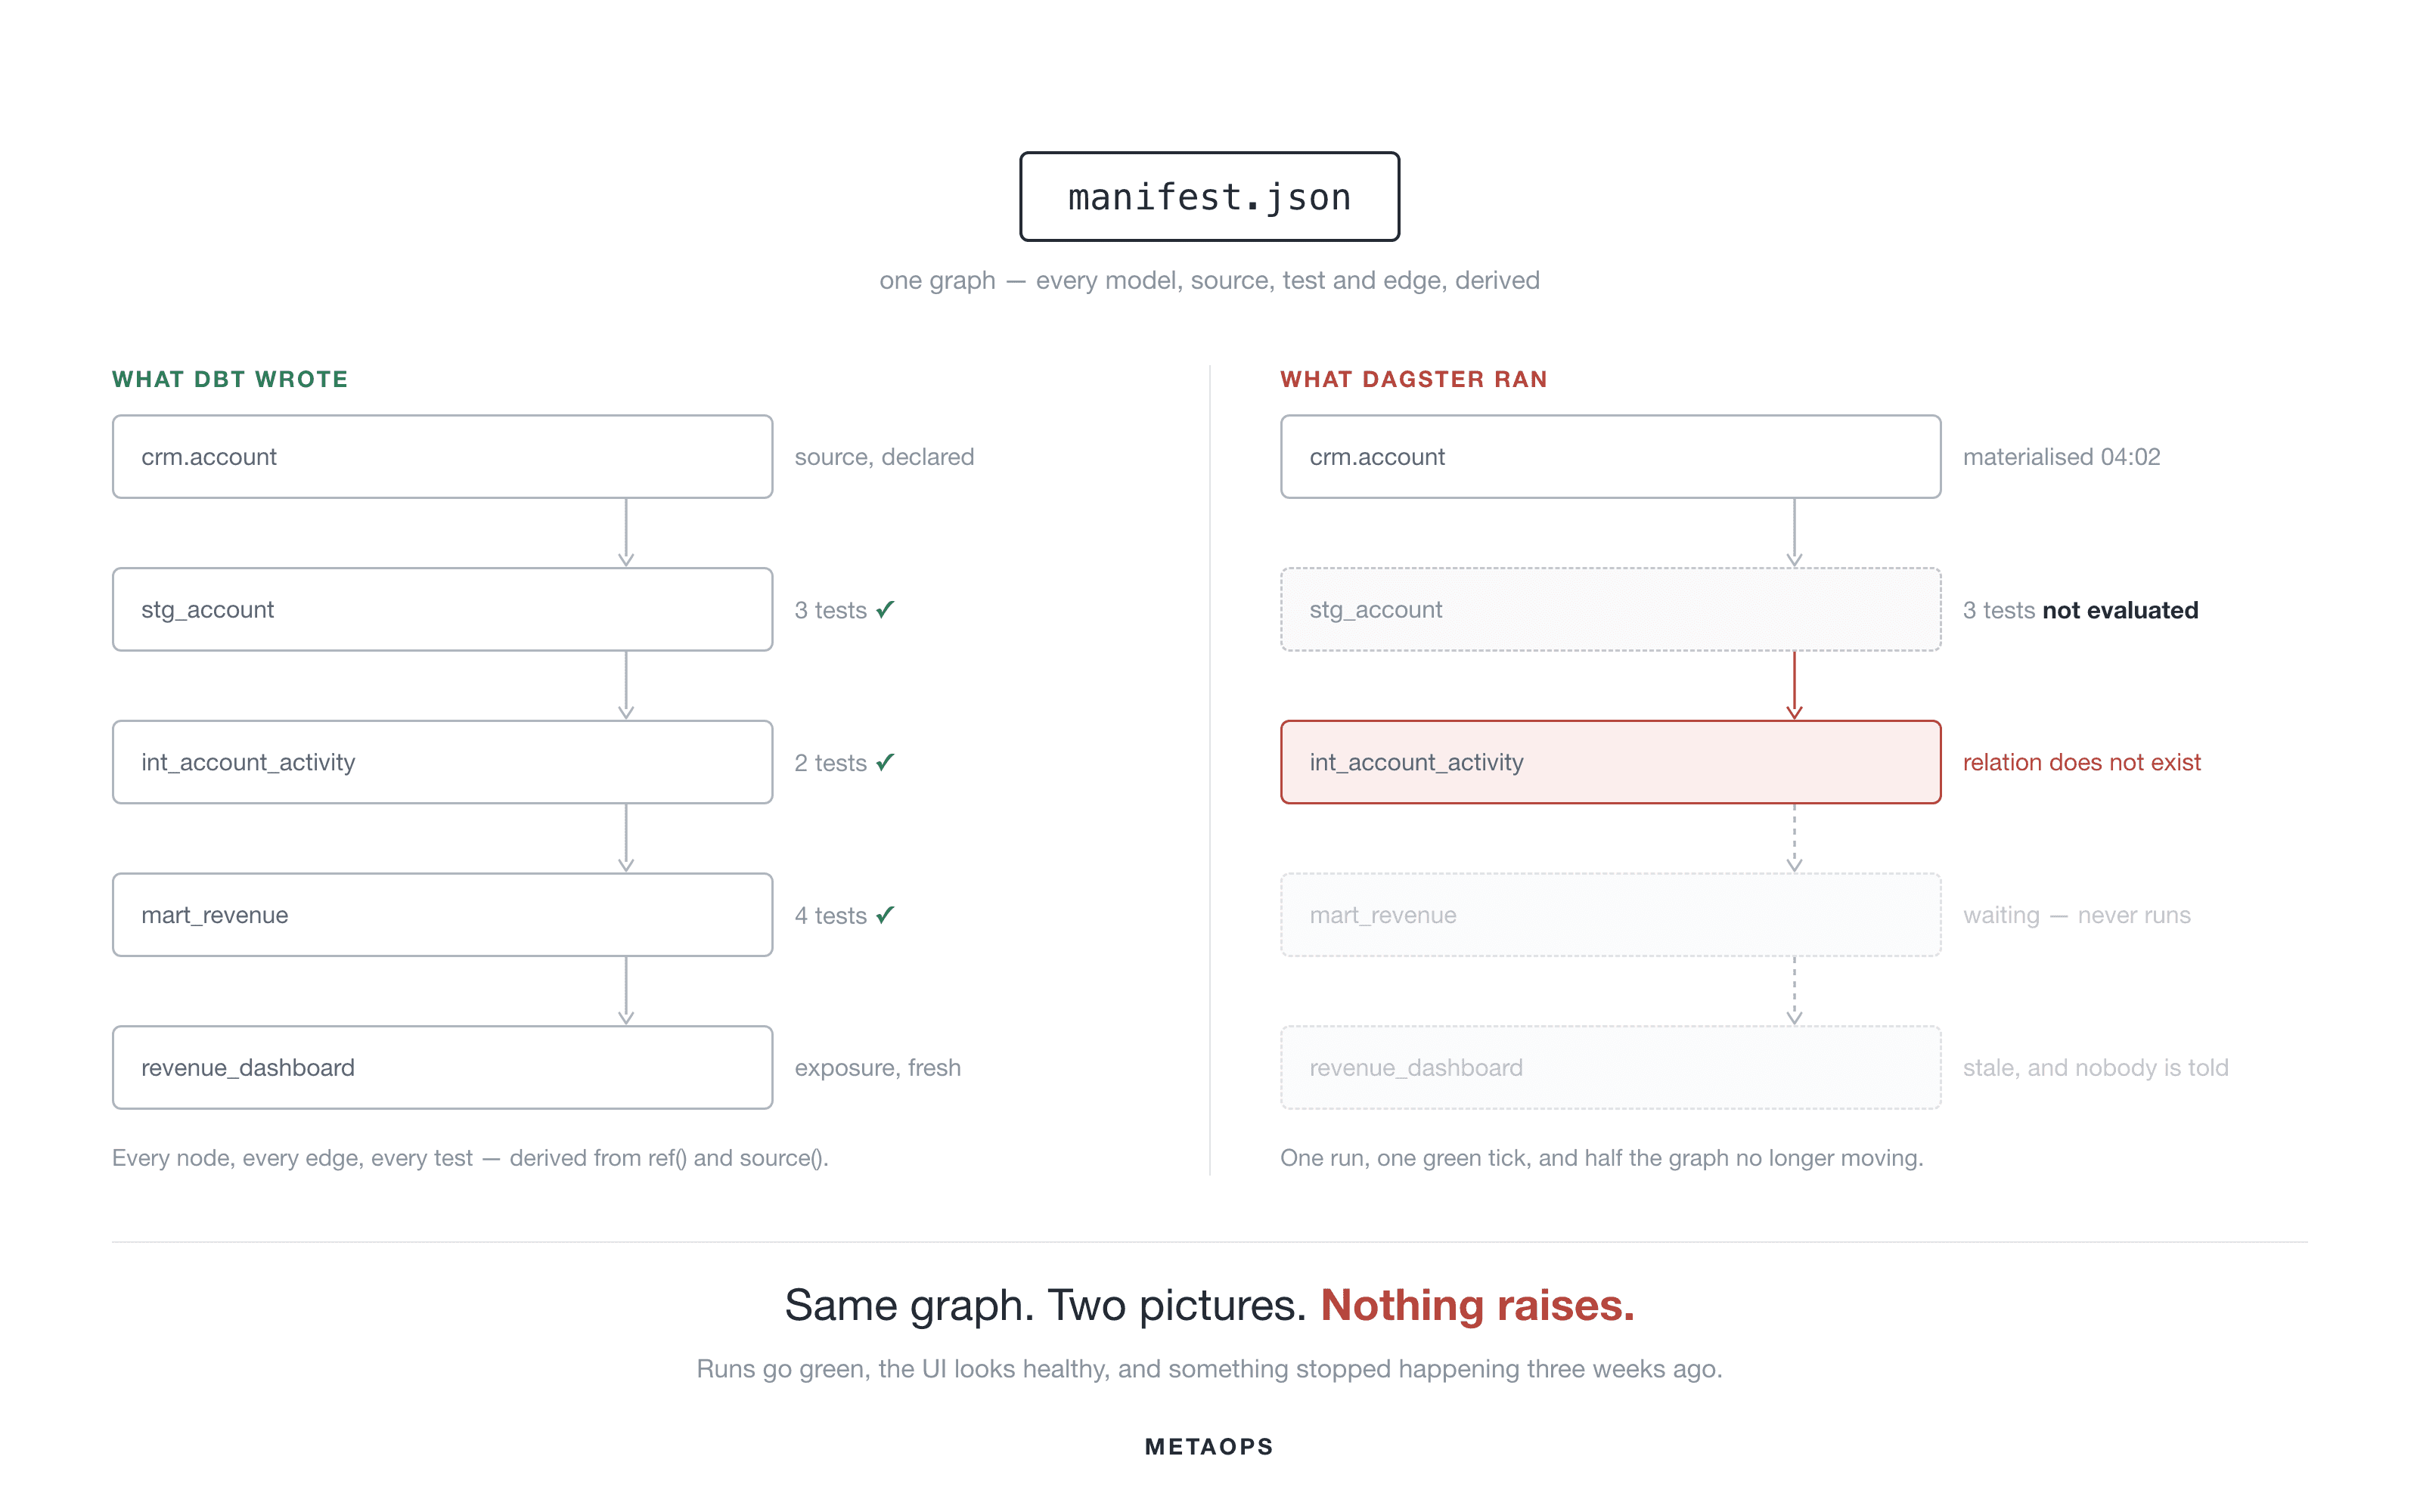
dbt already writes the whole dependency graph to manifest.json, and dagster-dbt turns it into assets, checks and scheduling policy. Getting that working takes an afternoon; keeping it working is the interesting part. Eight places the two pictures drift apart, all with the same shape — nothing raises, runs go green, and something stopped happening three weeks ago.
Written By
Andrey Kozichev
data engineering
Sep 3, 2026
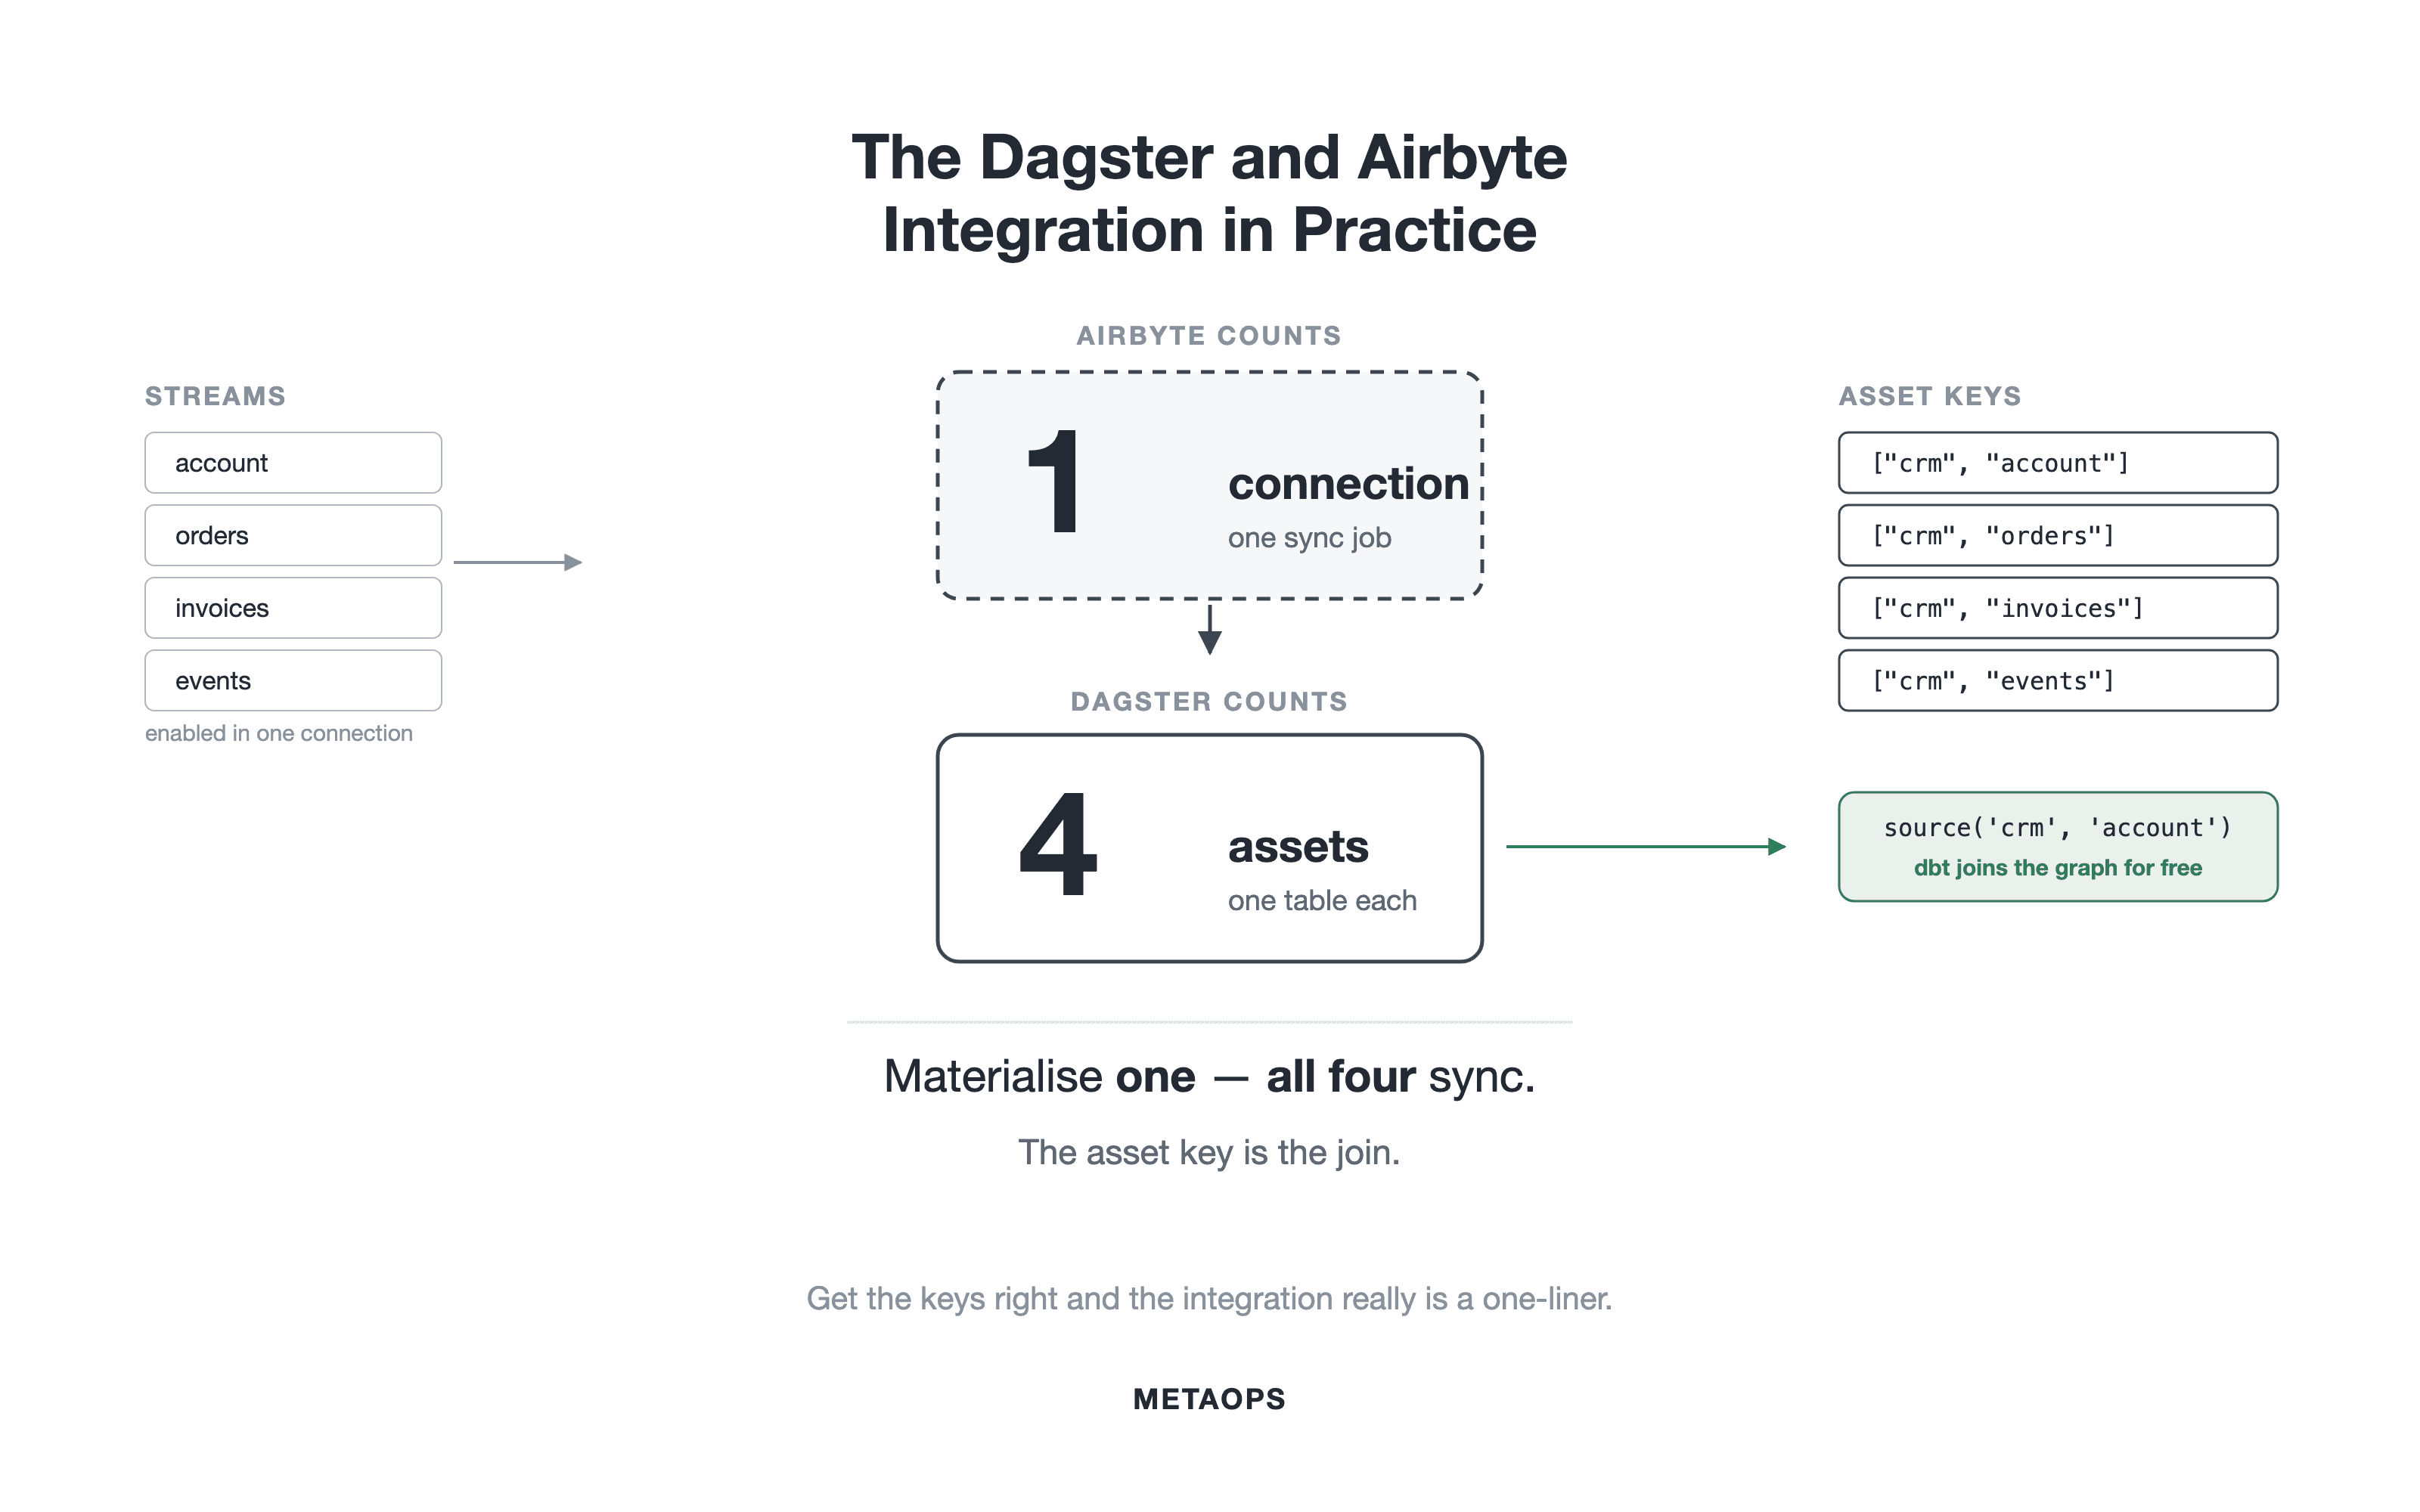
Airbyte's unit of work is a connection; Dagster's is a table. That single mismatch explains almost everything that surprises teams wiring the two together — why materialising one asset syncs four streams, why a duplicated stream stops the code loading, and why two schedulers quietly double your source load. Get the asset keys right and dbt joins the graph for free.
Written By
Abhivan Chekuri

data engineering
Aug 27, 2026
A general-purpose scheduler can run your dbt project, but it cannot see inside it. What goes wrong when cron expressions and hand-maintained dbt tags stand in for the dependency graph dbt already computes — and what an orchestrator would need to do instead.
Written By
Abhivan Chekuri

ai
Jun 29, 2026
Most AI failures in data pipelines aren't model failures — they're architecture failures. Ten anti-patterns for keeping LLMs out of the parts of your pipeline that need to be deterministic, cheap, and reproducible.
Written By
Andrey Kozichev
governance
May 19, 2026
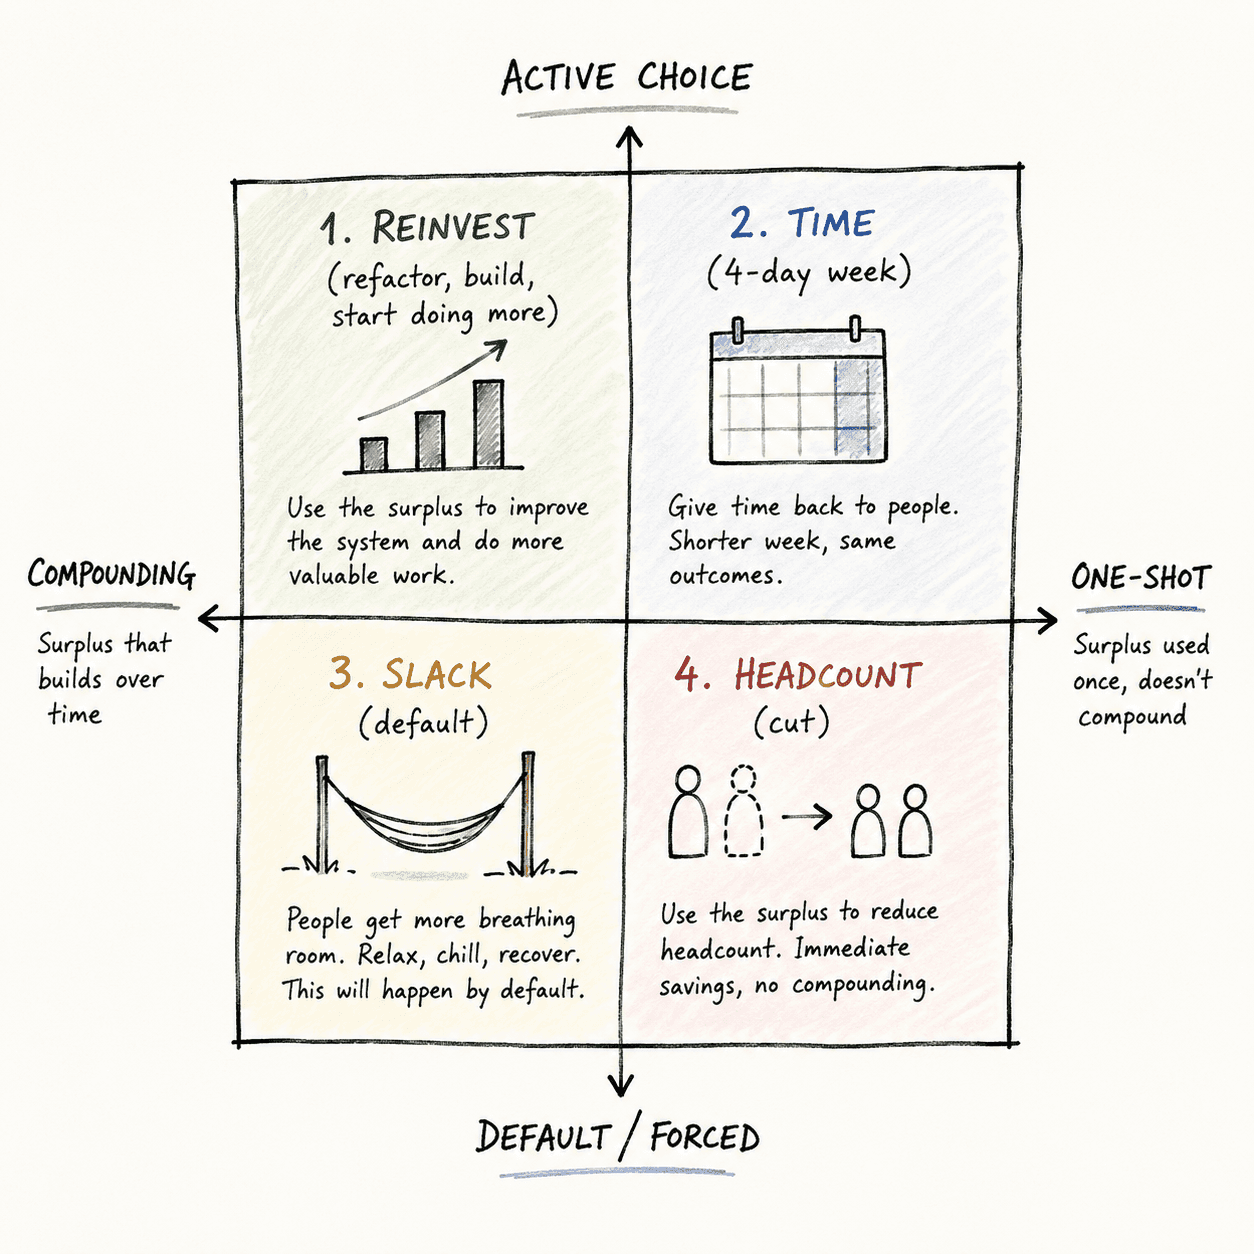
AI gave you a productivity surplus. You have four options for what to do with it — and two of them happen without you choosing. Here's the decision.
Written By
Andrey Kozichev
governance
Oct 30, 2025
Ever inherited a data platform where nobody knows how schemas evolved, configurations vanish after migrations, and 500+ models have no lineage? While software development embraced DevOps years ago, data engineering got left behind - stuck with clickops, tribal knowledge, and the dangerous myth that "we'll automate later." We rebuilt our data platforms with a code-first approach using Terraform, dbt, and GitOps, achieving an 80% reduction in manual work and transforming unreliable deployments into boring, repeatable operations. Here's why if it's not in code, it doesn't exist - and why that principle saved our infrastructure.
Written By
Andrey Kozichev

